Pytorch模型可视化

Pytorch模型可视化

Pytorch模型可视化

原文参考:pytorch模型网络可视化画图工具合集(内附实现代码)

用于可视化的模型

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
import torch
from torch import nn

class TinyVGG3D(nn.Module):
def __init__(self, input_channels: int, hidden_units: int, output_shape: int) -> None:
super().__init__()

self.input_channels = input_channels
self.hidden_units = hidden_units

# 第一个卷积块
self.conv_block_1 = nn.Sequential(
nn.Conv3d(in_channels=input_channels,
out_channels=hidden_units,
kernel_size=3,
stride=1,
padding=1),
nn.BatchNorm3d(hidden_units), #批归一化
nn.ReLU(inplace=True),
nn.Conv3d(in_channels=hidden_units,
out_channels=hidden_units,
kernel_size=3,
stride=1,
padding=1),
nn.BatchNorm3d(hidden_units),
nn.ReLU(inplace=True),
nn.MaxPool3d(kernel_size=2, stride=2) # 128->64
)

# 第二个卷积块
self.conv_block_2 = nn.Sequential(
nn.Conv3d(hidden_units, hidden_units*2, kernel_size=3, padding=1),
nn.BatchNorm3d(hidden_units * 2),
nn.ReLU(inplace=True),
nn.Conv3d(hidden_units*2, hidden_units*2, kernel_size=3, padding=1),
nn.BatchNorm3d(hidden_units * 2),
nn.ReLU(inplace=True),
nn.MaxPool3d(kernel_size=2, stride=2) # 64->32
)

# 第三个卷积块
self.conv_block_3 = nn.Sequential(
nn.Conv3d(hidden_units * 2, hidden_units * 4, kernel_size=3, padding=1),
nn.BatchNorm3d(hidden_units * 4),
nn.ReLU(inplace=True),
nn.Conv3d(hidden_units * 4, hidden_units * 4, kernel_size=3, padding=1),
nn.BatchNorm3d(hidden_units * 4),
nn.ReLU(inplace=True),
nn.MaxPool3d(kernel_size=2, stride=2) # 32->16
)

self.adaptive_pool = nn.AdaptiveAvgPool3d((4, 4, 4)) # 自适应平均池化,减少参数量

self.classifier = nn.Sequential(
nn.Flatten(),
nn.Linear(hidden_units * 4 * 4 * 4 * 4, 128), # 固定输入维度
nn.ReLU(inplace=True),
nn.Dropout(0.5),
nn.Linear(128, 64),
nn.ReLU(inplace=True),
nn.Dropout(0.3),
nn.Linear(64, output_shape)
)

def forward(self, x: torch.Tensor) -> torch.Tensor:
"""
前向传播

Args:
x: 输入张量,形状为 (batch_size, channels, depth, height, width)

Returns:
输出张量,形状为 (batch_size, 1)
"""
# 确保输入维度正确
if x.dim() == 4: # 如果输入是4D,添加通道维度
x = x.unsqueeze(1)

x = self.conv_block_1(x)
x = self.conv_block_2(x)
x = self.conv_block_3(x)
x = self.adaptive_pool(x) # 自适应池化
x = self.classifier(x)

return x # 返回 (batch_size, 1) 形状

def get_model_info(self):
"""获取模型信息"""
total_params = sum(p.numel() for p in self.parameters())
trainable_params = sum(p.numel() for p in self.parameters() if p.requires_grad)

return {
'total_parameters': total_params,
'trainable_parameters': trainable_params,
'model_size_mb': total_params * 4 / (1024 * 1024) # 假设float32
}

torch print

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
from PytorchModelView.model_builder import TinyVGG3D
import torch

model = TinyVGG3D(input_channels=1, hidden_units=32, output_shape=1)
print(model)

# 创建测试输入
test_input = torch.randn(2, 1, 128, 128, 128) # batch_size=2

# 前向传播
with torch.no_grad():
output = model(test_input)
print(f"输入形状: {test_input.shape}")
print(f"输出形状: {output.shape}")
print(f"输出值: {output}")

# 打印模型信息
info = model.get_model_info()
print(f"\n模型信息:")
print(f"总参数量: {info['total_parameters']:,}")
print(f"可训练参数: {info['trainable_parameters']:,}")
print(f"模型大小: {info['model_size_mb']:.2f} MB")
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
TinyVGG3D(
(conv_block_1): Sequential(
(0): Conv3d(1, 32, kernel_size=(3, 3, 3), stride=(1, 1, 1), padding=(1, 1, 1))
(1): BatchNorm3d(32, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True)
(2): ReLU(inplace=True)
(3): Conv3d(32, 32, kernel_size=(3, 3, 3), stride=(1, 1, 1), padding=(1, 1, 1))
(4): BatchNorm3d(32, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True)
(5): ReLU(inplace=True)
(6): MaxPool3d(kernel_size=2, stride=2, padding=0, dilation=1, ceil_mode=False)
)
(conv_block_2): Sequential(
(0): Conv3d(32, 64, kernel_size=(3, 3, 3), stride=(1, 1, 1), padding=(1, 1, 1))
(1): BatchNorm3d(64, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True)
(2): ReLU(inplace=True)
(3): Conv3d(64, 64, kernel_size=(3, 3, 3), stride=(1, 1, 1), padding=(1, 1, 1))
(4): BatchNorm3d(64, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True)
(5): ReLU(inplace=True)
(6): MaxPool3d(kernel_size=2, stride=2, padding=0, dilation=1, ceil_mode=False)
)
(conv_block_3): Sequential(
(0): Conv3d(64, 128, kernel_size=(3, 3, 3), stride=(1, 1, 1), padding=(1, 1, 1))
(1): BatchNorm3d(128, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True)
(2): ReLU(inplace=True)
(3): Conv3d(128, 128, kernel_size=(3, 3, 3), stride=(1, 1, 1), padding=(1, 1, 1))
(4): BatchNorm3d(128, eps=1e-05, momentum=0.1, affine=True, track_running_stats=True)
(5): ReLU(inplace=True)
(6): MaxPool3d(kernel_size=2, stride=2, padding=0, dilation=1, ceil_mode=False)
)
(adaptive_pool): AdaptiveAvgPool3d(output_size=(4, 4, 4))
(classifier): Sequential(
(0): Flatten(start_dim=1, end_dim=-1)
(1): Linear(in_features=8192, out_features=128, bias=True)
(2): ReLU(inplace=True)
(3): Dropout(p=0.5, inplace=False)
(4): Linear(in_features=128, out_features=64, bias=True)
(5): ReLU(inplace=True)
(6): Dropout(p=0.3, inplace=False)
(7): Linear(in_features=64, out_features=1, bias=True)
)
)
输入形状: torch.Size([2, 1, 128, 128, 128])
输出形状: torch.Size([2, 1])
输出值: tensor([[0.0573],
[0.1844]])

模型信息:
总参数量: 1,916,321
可训练参数: 1,916,321
模型大小: 7.31 MB

torchsummary torchinfo

pytorch-summary

安装:pip install torchsummary
torchsummary目前不支持包维护了
推荐采用更现代化的torchinfo

安装:pip install torchinfo

1
2
3
4
5
6
7
8
9
#from torchsummary import summary#torchsummary包存在问题
from torchinfo import summary
from PytorchModelView.model_builder import TinyVGG3D
import torch

model = TinyVGG3D(input_channels=1, hidden_units=32, output_shape=1)
test_input = torch.randn(2, 1, 128, 128, 128)
summary(model, test_input.squeeze(dim=0).shape)
#summary(model, test_input)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
==========================================================================================
Layer (type:depth-idx) Output Shape Param #
==========================================================================================
TinyVGG3D [2, 1] --
├─Sequential: 1-1 [2, 32, 64, 64, 64] --
│ └─Conv3d: 2-1 [2, 32, 128, 128, 128] 896
│ └─BatchNorm3d: 2-2 [2, 32, 128, 128, 128] 64
│ └─ReLU: 2-3 [2, 32, 128, 128, 128] --
│ └─Conv3d: 2-4 [2, 32, 128, 128, 128] 27,680
│ └─BatchNorm3d: 2-5 [2, 32, 128, 128, 128] 64
│ └─ReLU: 2-6 [2, 32, 128, 128, 128] --
│ └─MaxPool3d: 2-7 [2, 32, 64, 64, 64] --
├─Sequential: 1-2 [2, 64, 32, 32, 32] --
│ └─Conv3d: 2-8 [2, 64, 64, 64, 64] 55,360
│ └─BatchNorm3d: 2-9 [2, 64, 64, 64, 64] 128
│ └─ReLU: 2-10 [2, 64, 64, 64, 64] --
│ └─Conv3d: 2-11 [2, 64, 64, 64, 64] 110,656
│ └─BatchNorm3d: 2-12 [2, 64, 64, 64, 64] 128
│ └─ReLU: 2-13 [2, 64, 64, 64, 64] --
│ └─MaxPool3d: 2-14 [2, 64, 32, 32, 32] --
├─Sequential: 1-3 [2, 128, 16, 16, 16] --
│ └─Conv3d: 2-15 [2, 128, 32, 32, 32] 221,312
│ └─BatchNorm3d: 2-16 [2, 128, 32, 32, 32] 256
│ └─ReLU: 2-17 [2, 128, 32, 32, 32] --
│ └─Conv3d: 2-18 [2, 128, 32, 32, 32] 442,496
│ └─BatchNorm3d: 2-19 [2, 128, 32, 32, 32] 256
│ └─ReLU: 2-20 [2, 128, 32, 32, 32] --
│ └─MaxPool3d: 2-21 [2, 128, 16, 16, 16] --
├─AdaptiveAvgPool3d: 1-4 [2, 128, 4, 4, 4] --
├─Sequential: 1-5 [2, 1] --
│ └─Flatten: 2-22 [2, 8192] --
│ └─Linear: 2-23 [2, 128] 1,048,704
│ └─ReLU: 2-24 [2, 128] --
│ └─Dropout: 2-25 [2, 128] --
│ └─Linear: 2-26 [2, 64] 8,256
│ └─ReLU: 2-27 [2, 64] --
│ └─Dropout: 2-28 [2, 64] --
│ └─Linear: 2-29 [2, 1] 65
==========================================================================================
Total params: 1,916,321
Trainable params: 1,916,321
Non-trainable params: 0
Total mult-adds (G): 250.40
==========================================================================================
Input size (MB): 16.78
Forward/backward pass size (MB): 5637.15
Params size (MB): 7.67
Estimated Total Size (MB): 5661.59
==========================================================================================

graphviz的安装

支持查看dot转为图像
在线:http://magjac.com/graphviz-visual-editor/
win需要本地安装:https://graphviz.org/download/
可以生成dot文件,pycharm中有dotsupport插件可以查看
pycharm设置:设置→工具→dot support→选择graphviz安装路径中bin的dot.exe
在conda中也需要安装:conda install -c conda-forge graphviz

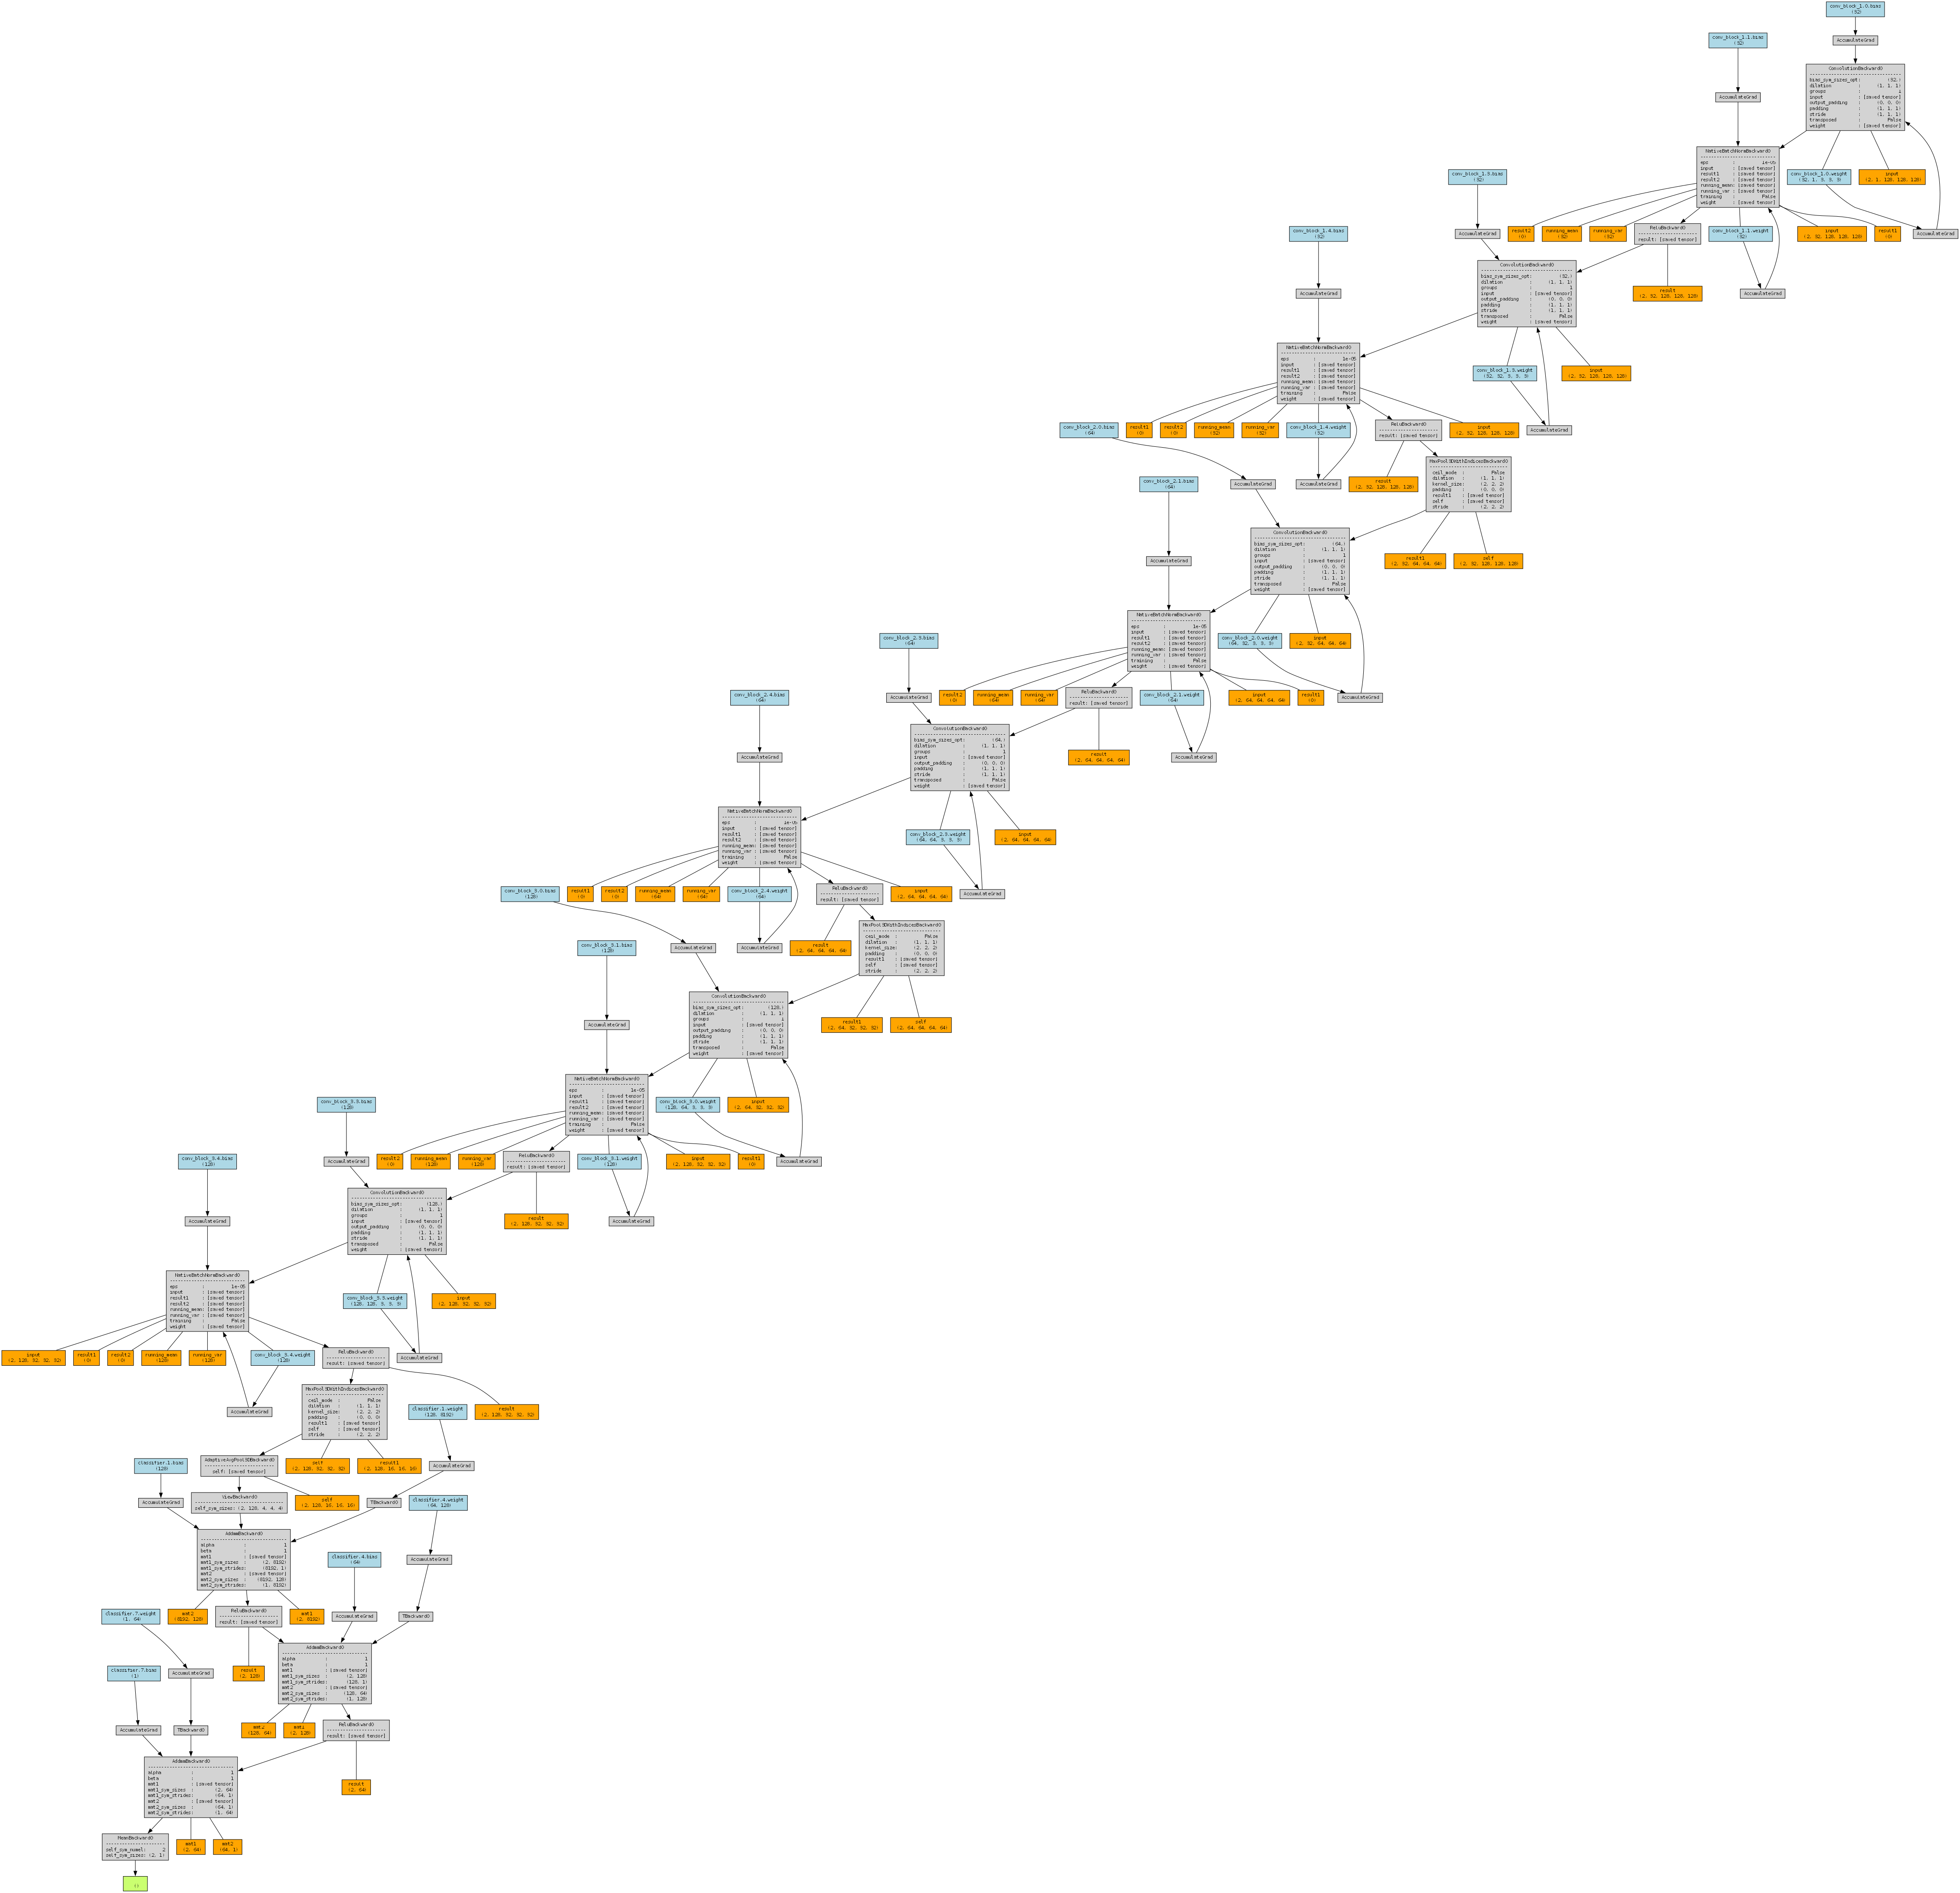
torchviz

pytorchviz

安装:pip install torchviz
需要安装graphviz

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
from torchviz import make_dot
from PytorchModelView.model_builder import TinyVGG3D
import torch

import os
import sys
# 添加Graphviz路径(替换为您的实际路径)
graphviz_path = r"C:\Program Files\Graphviz\bin"
if graphviz_path not in os.environ["PATH"]:
os.environ["PATH"] += os.pathsep + graphviz_path

# 创建模型和测试输入
model = TinyVGG3D(input_channels=1, hidden_units=32, output_shape=1)
test_input = torch.randn(2, 1, 128, 128, 128)

# 前向传播
model.eval()
output = model(test_input)
# 生成计算图可视化
#dot = make_dot(output, params=dict(model.named_parameters()), show_attrs=True, show_saved=True)
dot = make_dot(model(test_input).mean(), params=dict(model.named_parameters()), show_attrs=True, show_saved=True)

# 保存为文件
dot.format = 'png' # 可以是 'png', 'pdf', 'svg' 等
output.directory = "."
dot.render('model_graph_torchviz', cleanup=True) # 生成 model_graph.png

print("计算图已保存为 model_graph.png")
print(f"模型输出形状: {output.shape}")

hiddenlayer

hiddenlayer跟之前比的一个特色在于,hiddenlayer中支持transforms配置,可以对指定的多个连续算子进行fusion展示,以及有多个重复的结构的话可以进行fold压缩展示。

安装:pip install hiddenlayer

测试失败,放弃使用,软件包较久没有维护

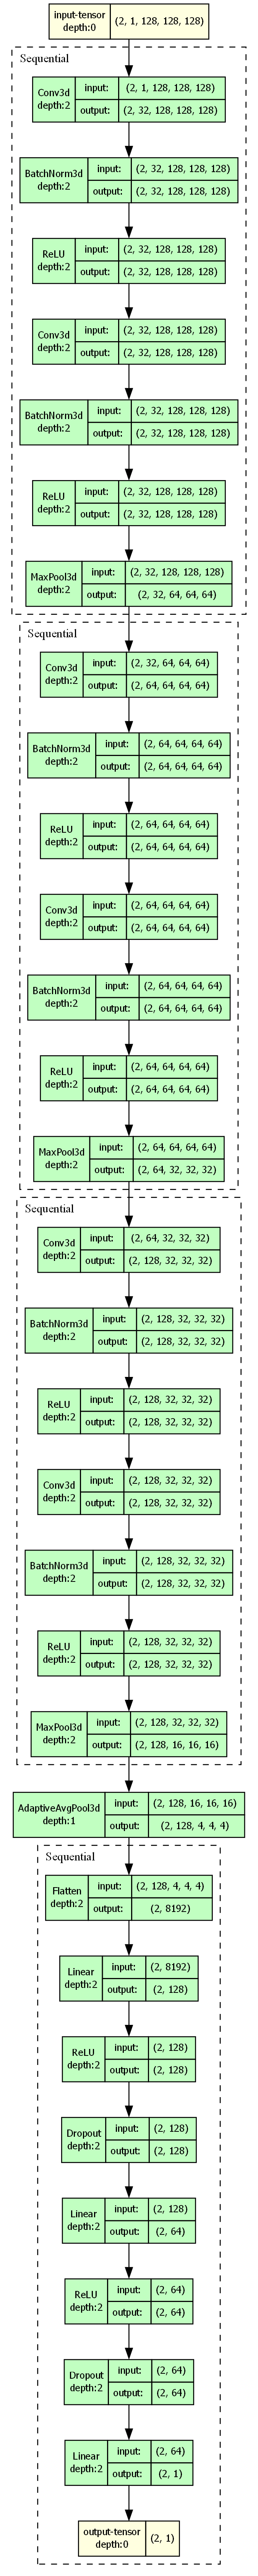
torchview

网址:https://github.com/mert-kurttutan/torchview

安装:pip install graphviz+pip install torchview

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
import torch
from PytorchModelView.model_builder import TinyVGG3D
from torchview import draw_graph

import os
import sys
# 添加Graphviz路径(替换为您的实际路径)
graphviz_path = r"C:\Program Files\Graphviz\bin"
if graphviz_path not in os.environ["PATH"]:
os.environ["PATH"] += os.pathsep + graphviz_path

model = TinyVGG3D(input_channels=1, hidden_units=32, output_shape=1)
test_input = torch.randn(2, 1, 128, 128, 128)

model_graph = draw_graph(model, input_size=test_input.shape, expand_nested=True, save_graph=True, filename="torchview_test", directory=".")
model_graph.visual_graph

# 保存一个dot和一个低质量的png
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
import torch
from PytorchModelView.model_builder import TinyVGG3D
from torchview import draw_graph

import os
import sys
# 添加Graphviz路径(替换为您的实际路径)
graphviz_path = r"C:\Program Files\Graphviz\bin"
if graphviz_path not in os.environ["PATH"]:
os.environ["PATH"] += os.pathsep + graphviz_path

model = TinyVGG3D(input_channels=1, hidden_units=32, output_shape=1)
test_input = torch.randn(2, 1, 128, 128, 128)

model_graph = draw_graph(model, input_size=test_input.shape, expand_nested=True, save_graph=False, filename="torchview_test", directory=".")
#model_graph.visual_graph

# 调整参数提高图片质量
# model_graph = draw_graph(
# model,
# input_size=test_input.shape,
# expand_nested=True,
# save_graph=False, #暂时不保存
# filename="torchview_test",
# directory=".",
# # 关键参数:调整图片质量
# graph_name="torchview_test",
# graph_dir="TB", # 从上到下布局
# hide_module_functions=False,
# hide_inner_tensors=False,
# roll=False,
# show_shapes=True,
# show_layer_names=True
# )

# 手动设置高DPI并保存
dot = model_graph.visual_graph
dot.attr(dpi='300') # 设置300 DPI
dot.render('torchview_test', format='png', cleanup=True)

# 保存一个高质量的png

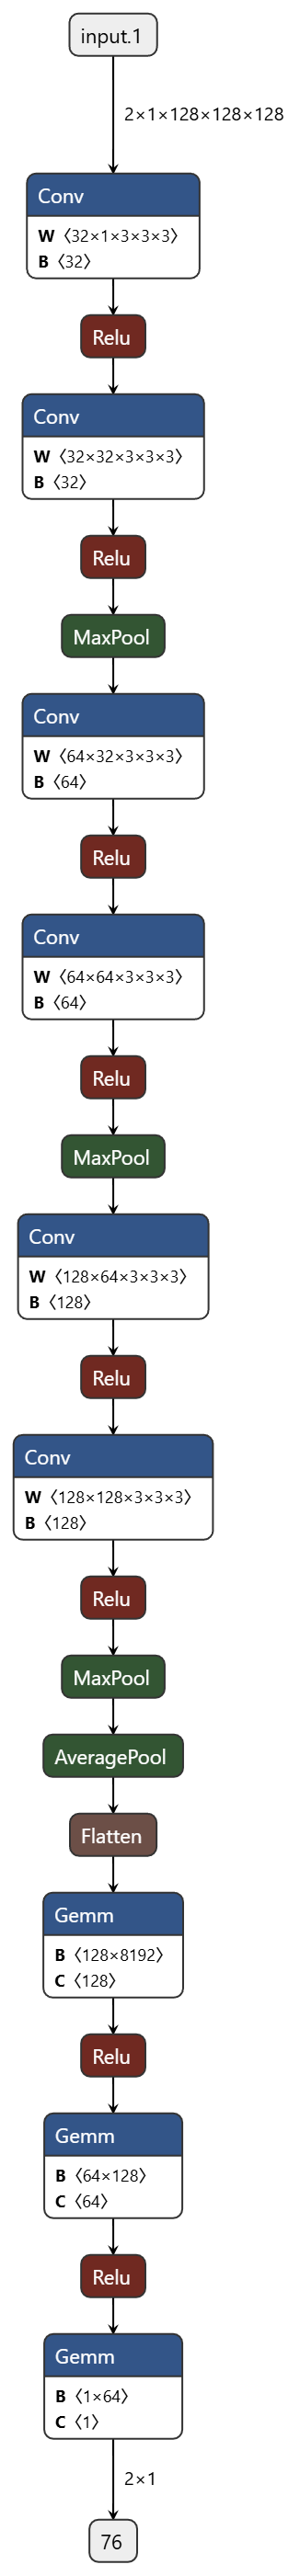
netron

网址:https://github.com/lutzroeder/netron

安装:pip install onnx + pip install netron

本地下载软件

会生成.onnx文件,然后导入到本地文件中可以看到
也可以使用代码直接在浏览器中打开

1
2
3
4
5
6
7
8
9
10
11
12
import torch
from PytorchModelView.model_builder import TinyVGG3D
import netron

model = TinyVGG3D(input_channels=1, hidden_units=32, output_shape=1)
test_input = torch.randn(2, 1, 128, 128, 128)

onnx_file_path = "netron_test.onnx"
torch.onnx.export(model, test_input, onnx_file_path, verbose=True)

# 启动netron服务器查看模型
netron.start('netron_test.onnx', port=8080)

PlotNeuralNet

项目原来地址:https://github.com/HarisIqbal88/PlotNeuralNet

个人感觉像是一个css管理器,可以自定义模块颜色,然后通过设置参数进行图像输出
需要对模型比较了解,绘图风格较好

直接将原项目复制到本地,新建文件夹进行创建运行。

如果需要修改已有的模块或者新建模块,可以在pycore→blocks.py+tikzeng.py中修改

下图为一个GAN三维生成器的视图

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
import sys

sys.path.append('../')
from pycore.tikzeng import *

arch = [
to_head('..'),
to_cor(),
to_begin(),

# ============ 输入层 ============
to_Start(name="z",
s_filer="",
n_filer="100",
offset="(0,0,0)",
to="(0,0,0)",
height=50,
depth=1,
width=1,
caption="z"),

# ============ 全连接层 ============
to_FullCon(name="fc",
s_filer="8x8x8",
n_filer="256",
offset="(2,0,0)",
to="(z-east)",
height=100,
depth=1,
width=1,
caption="FC"),
to_connection("z", "fc"),
to_connection_expand("z", "fc"),

# ============ Reshape ============
to_ConvRelu(name="reshape",
s_filer="8 x 8 x 8",
n_filer=256,
offset="(2.5,0,0)",
to="(fc-east)",
height=100,
depth=8,
width=8,
caption="Reshape"),
to_connection("fc", "reshape"),
to_connection_expand("fc", "reshape"),

# ============ Block 1: 8³ -> 16³ ============
to_ConvRelu(name="convt1",
s_filer="16 x 16 x 16",
n_filer=128,
offset="(2.5,0,0)",
to="(reshape-east)",
height=80,
depth=16,
width=16,
caption="ConvT3D-1"),
to_connection("reshape", "convt1"),

# ============ Block 2: 16³ -> 32³ ============
to_ConvRelu(name="convt2",
s_filer="32 x 32 x 32",
n_filer=64,
offset="(2.5,0,0)",
to="(convt1-east)",
height=64,
depth=32,
width=32,
caption="ConvT3D-2"),
to_connection("convt1", "convt2"),

# ============ Block 3: 32³ -> 64³ ============
to_ConvRelu(name="convt3",
s_filer="64 x 64 x 64",
n_filer=32,
offset="(2.5,0,0)",
to="(convt2-east)",
height=45,
depth=25,
width=25,
caption="ConvT3D-3"),
to_connection("convt2", "convt3"),

# ============ Block 4: 64³ -> 128³ ============
to_ConvRelu(name="convt4",
s_filer="128 x 128 x 128",
n_filer=1,
offset="(2.5,0,0)",
to="(convt3-east)",
height=32,
depth=32,
width=32,
caption="ConvT3D-4"),
to_connection("convt3", "convt4"),

# ============ Sigmoid ============
to_Pool(name="sig",
offset="(0,0,0)",
to="(convt4-east)",
height=32,
depth=32,
width=3,
caption="Sigmoid"),

# ============ output ============
to_Output(name="output",
s_filer="128 x 128 x 128",
n_filer="1",
offset="(2,0,0)",
to="(sig-east)",
height=32,
depth=32,
width=32,
caption="Output"),
to_connection("sig", "output"),

to_end()
]

def main():
namefile = str(sys.argv[0]).split('.')[0]
to_generate(arch, namefile + '.tex')


if __name__ == '__main__':
main()

生成一个tex文件,使用latex编辑器打开后可以生成pdf然后导出为png
总结

文字信息可以用print直接打印
出图可以用torchview和netron

文章作者: HibisciDai
文章链接: http://hibiscidai.com/2026/09/28/Pytorch模型可视化/
版权声明: 本博客所有文章除特别声明外,均采用 CC BY-NC-SA 4.0 许可协议。转载请注明来自 HibisciDai!